Error Handling Policies
When a subscriber throws while processing a consumed message, or the message cannot be deserialized, decrypted or validated, Silverback applies the error policy configured for the consumer endpoint. Error policies let you retry the processing, skip the message, move it to another topic, or stop the consumer.
This guide covers the built-in policies, how to combine them, and the caveats to be aware of.
Note
Stopping the consumer (e.g. when the application shuts down) cancels the CancellationToken passed to the subscribers. If a subscriber throws an OperationCanceledException because of that cancellation, the error policies aren't applied: the message is rolled back, without being committed (Kafka) or acknowledged (MQTT), to be consumed again. Any other OperationCanceledException (e.g. a timed out HTTP request) is handled by the error policies like any other exception.
Default Behavior
If no error policy is configured, the StopConsumerErrorPolicy is applied: the exception is logged and the consumer is stopped and disconnected. The failed message isn't committed (Kafka) or acknowledged (MQTT), so it will be consumed again once the consumer is restarted.
This is a safe default, because no message is ever lost, but a single faulty message (a so-called poison message) will block the consumer until the issue is fixed. In most cases you will want to configure an explicit policy.
Configure a Policy
The error policy is configured per endpoint, using OnError.
services.AddSilverback()
    .WithConnectionToMessageBroker(options => options.AddKafka())
    .AddKafkaClients(clients => clients
        .WithBootstrapServers("PLAINTEXT://localhost:9092")
        .AddConsumer("consumer1", consumer => consumer
            .WithGroupId("my-group")
            .Consume<MyMessage>("endpoint1", endpoint => endpoint
                .ConsumeFrom("my-topic")
                .OnError(policy => policy.Retry(3).ThenSkip()))));
The OnError method accepts either a builder action (receiving an IErrorPolicyBuilder) or an IErrorPolicy instance (see Custom Policies).
Built-in Policies
| Policy | Builder method | Effect |
|---|---|---|
| StopConsumerErrorPolicy | Stop() |
Stops the consumer (default). The message isn't committed. |
| SkipMessageErrorPolicy | Skip() |
Logs the error, ignores the message and commits it, so that the consumer can proceed with the next one. |
| RetryErrorPolicy | Retry() |
Rolls back and processes the same message again, optionally after a delay. |
| MoveMessageErrorPolicy | MoveTo(...) |
Produces the failed message to another endpoint (or to the end of the same topic) and commits it. |
Stop
.OnError(policy => policy.Stop())
Explicitly configuring Stop() is only useful as the last element of a chain, or in combination with the apply rules to stop the consumer only for specific exceptions.
Skip
.OnError(policy => policy.Skip())
Warning
The skipped message is lost. Combine Skip() with logging or with the callbacks if you need to keep track of the skipped messages, or use MoveTo to park them in a dead letter topic instead.
Retry
.OnError(policy => policy.Retry(5))
The retries count specifies how many times the processing will be retried; Retry(5) results in up to 6 processing attempts in total. You can alternatively specify the count with WithMaxRetries:
.OnError(policy => policy.Retry(retryPolicy => retryPolicy.WithMaxRetries(5)))
Important
Retry() without a retries count retries indefinitely, until the processing succeeds.
If the processing still fails after the last retry, the next policy in the chain is applied. If there is no next policy, the consumer is stopped.
Retry Delay
By default, the message is retried immediately. Use one of the following methods of the RetryErrorPolicyBuilder to delay the retries:
WithInterval(TimeSpan interval): waits a fixed interval before each retry.WithIncrementalDelay(TimeSpan initialDelay, TimeSpan delayIncrement, TimeSpan? maxDelay = null): waits the initial delay before the first retry and adds the increment at each subsequent retry, optionally capping the delay tomaxDelay.WithExponentialDelay(TimeSpan initialDelay, double delayFactor, TimeSpan? maxDelay = null): waits the initial delay before the first retry and multiplies it by the factor at each subsequent retry, optionally capping the delay tomaxDelay.
.OnError(policy => policy
    .Retry(3, retryPolicy => retryPolicy.WithInterval(TimeSpan.FromSeconds(1)))
    .ThenSkip())
.OnError(policy => policy
    .Retry(10, retryPolicy => retryPolicy
        .WithExponentialDelay(
            TimeSpan.FromMilliseconds(100),
            2,
            TimeSpan.FromSeconds(30)))
    .ThenMoveTo("my-topic-dlq"))
In this example, the retries are delayed by 100 milliseconds, 200 milliseconds, 400 milliseconds and so on, up to 30 seconds.
Important
The delay is applied in-process, while the consumer holds on to the failed message: no further message is processed from the same partition (Kafka) or by the same processing channel (MQTT) in the meantime. Long delays can therefore cause broker timeouts. See Kafka Considerations and MQTT Considerations.
Move
The MoveTo policy produces the failed message to another endpoint and then commits it, so that the consumer can proceed. A typical use case is a dead letter topic, where the failed messages are parked for later analysis or reprocessing.
The endpoint name can be either the name of a topic or the friendly name of an endpoint configured in a producer. In both cases a producer endpoint must be configured: Silverback uses that producer (and its configuration, including the serializer) to produce the moved message.
services.AddSilverback()
    .WithConnectionToMessageBroker(options => options.AddKafka())
    .AddKafkaClients(clients => clients
        .WithBootstrapServers("PLAINTEXT://localhost:9092")
        .AddProducer("producer1", producer => producer
            .Produce<MyMessage>("dead-letter", endpoint => endpoint
                .ProduceTo("my-topic-dlq")))
        .AddConsumer("consumer1", consumer => consumer
            .WithGroupId("my-group")
            .Consume<MyMessage>("endpoint1", endpoint => endpoint
                .ConsumeFrom("my-topic")
                .OnError(policy => policy
                    .Retry(3)
                    .ThenMoveTo("dead-letter")))));
Note
If the moved message was successfully deserialized, the deserialized message is serialized again by the destination producer. Otherwise (for example, if the deserialization failed), the raw message is moved as-is. The original headers are preserved.
Transform the Moved Message
Use Transform to modify the outbound envelope before it is produced, for example to add some headers. An overload also receives the exception.
.OnError(policy => policy
    .MoveTo(
        "dead-letter",
        movePolicy => movePolicy
            .Transform((envelope, exception) => envelope?.AddOrReplaceHeader("x-error-message", exception.Message))))
Move to the Same Topic
Moving the message to the end of the same topic is a way to retry it later without blocking the consumption of the subsequent messages. In this case, limit the number of attempts with WithMaxRetries, otherwise a message that keeps failing will be moved over and over.
.OnError(policy => policy
    .MoveTo(
        "my-topic",
        movePolicy => movePolicy.WithMaxRetries(10))
    .ThenSkip())
The failed attempts count travels with the moved message in the x-failed-attempts header (see Failed Attempts Header), allowing Silverback to keep counting when the message is consumed again.
Warning
Moving the message breaks the ordering guarantees: the moved message will be processed after the messages that were already in the destination topic.
Kafka Headers Added to the Moved Message
When moving a message consumed from Kafka, Silverback adds some headers describing the source of the message and the failure:
| Header | Content |
|---|---|
x-source-topic |
The topic the message was consumed from. |
x-source-partition |
The source partition. |
x-source-offset |
The source offset. |
x-source-timestamp |
The timestamp of the source message. |
x-source-consumer-group-id |
The consumer group id. |
x-failure-reason |
The type of the innermost exception and its source. |
The header names are defined in KafkaMessageHeaders and DefaultMessageHeaders. See also Default Headers.
Chaining Policies
Policies can be chained to define an escalation path. Start the chain with one of the IErrorPolicyBuilder methods (Stop, Skip, Retry, MoveTo) and continue with the corresponding Then* methods (ThenStop, ThenSkip, ThenRetry, ThenMoveTo).
.OnError(policy => policy
    .Retry(3, retryPolicy => retryPolicy.WithInterval(TimeSpan.FromSeconds(1)))
    .ThenRetry(5, retryPolicy => retryPolicy.WithInterval(TimeSpan.FromSeconds(30)))
    .ThenMoveTo("dead-letter"))
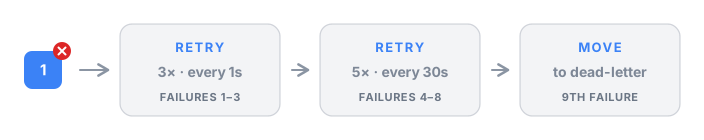
The policies are evaluated in order, each time the processing fails, and the first policy that can handle the error is applied. A policy is skipped if:
- its maximum number of attempts (
Retry(n),WithMaxRetries(n)) has been exceeded; - the exception doesn't match its apply rules;
- the policy can't handle the message (for example,
MoveTocan't move a sequence).
The maximum attempts of the chained policies are cumulative. In the example above, the first policy handles the first 3 failures, the second policy the next 5, and the message is moved after the ninth failed attempt.
Important
If none of the policies in the chain can handle the error, the exception is rethrown and the consumer is stopped, exactly as with the default policy. End the chain with Skip, MoveTo (without a limit), or an unlimited Retry if the consumer must never stop.
Failed Attempts Header
Each time the processing fails, the consumer increments the failed attempts counter of the message and stores it in the x-failed-attempts header of the inbound envelope (DefaultMessageHeaders.FailedAttempts). The error policies use this value to determine whether their maximum attempts have been reached, and the retry policy to compute the delay.
The counter is kept in memory by the consumer, using the header value as the starting point. Because of this:
- when a message is moved with
MoveTo, the header is produced along with it and the count continues when the message is consumed again; - the in-memory count isn't persisted: after a restart, a message that wasn't moved starts counting from zero again.
Note
MQTT 3.1.1 doesn't support headers, so the x-failed-attempts header can't be transferred with the moved message. For this reason, Silverback rejects a configuration that sets a maximum number of attempts on a policy other than Retry when using MQTT 3.1.1. See MQTT Client Configuration.
Apply Rules
By default, a policy is applied to any exception. Use the methods inherited from ErrorPolicyBaseBuilder<TBuilder> to restrict it:
ApplyTo<TException>()/ApplyTo(Type exceptionType): applies the policy only to the specified exception types (and their subclasses). Can be called multiple times.Exclude<TException>()/Exclude(Type exceptionType): never applies the policy to the specified exception types (and their subclasses). Can be called multiple times.ApplyWhen(Func<IRawInboundEnvelope, bool>)/ApplyWhen(Func<IRawInboundEnvelope, Exception, bool>): applies the policy only when the custom function returnstrue.
.OnError(policy => policy
    .Retry(5, retryPolicy => retryPolicy
        .ApplyTo<TimeoutException>()
        .ApplyTo<HttpRequestException>()
        .WithIncrementalDelay(TimeSpan.FromSeconds(1), TimeSpan.FromSeconds(1)))
    .ThenMoveTo(
        "dead-letter",
        movePolicy => movePolicy
            .Exclude<MyFatalException>()
            .ApplyWhen((envelope, exception) => !envelope.Headers.Contains("x-do-not-move")))
    .ThenStop())
In this example, only the transient errors are retried; all other errors (and the transient errors still failing after 5 retries) cause the message to be moved, unless it's a MyFatalException or the message carries the x-do-not-move header, in which case the consumer is stopped.
Note
The ApplyWhen function and the callbacks receive the IRawInboundEnvelope, not the deserialized message, since the error could have occurred before or during the deserialization. Cast it to IInboundEnvelope to access the deserialized message, when available.
Callbacks
You can execute custom code when a policy is about to be applied, for example to store the skipped messages, raise an alert or collect metrics. Implement one or more of the following interfaces and register the class with AddSingletonErrorPolicyCallback, AddScopedErrorPolicyCallback or AddTransientErrorPolicyCallback.
- ISkipMessageErrorPolicyCallback
Invoked when a message is about to be skipped. - IRetryErrorPolicyCallback
Invoked when a message is about to be retried. - IMoveMessageErrorPolicyCallback
Invoked when a message is about to be moved. - IStopConsumerErrorPolicyCallback
Invoked when the consumer is about to be stopped because of an error, either by theStoppolicy or because no policy could handle the error (e.g. after the last retry of aRetrypolicy not followed by any other policy).
services.AddSilverback()
    .WithConnectionToMessageBroker(options => options.AddKafka())
    .AddKafkaClients(...)
    .AddScopedErrorPolicyCallback<SkippedMessagesTracker>();
public class SkippedMessagesTracker : ISkipMessageErrorPolicyCallback
{
    private readonly IDeadLetterStore _store;

    public SkippedMessagesTracker(IDeadLetterStore store)
    {
        _store = store;
    }

    public Task OnSkippingMessageAsync(IRawInboundEnvelope envelope, Exception exception)
    {
        if (envelope.Endpoint.RawName != "orders")
            return Task.CompletedTask;

        return _store.SaveAsync(envelope, exception);
    }
}
The callbacks receive the envelope and the exception that caused the policy to be applied. Since they are invoked for all consumers, use the envelope (e.g. the endpoint or the message type) to decide whether to act.
The callbacks are invoked before the policy is applied: for example, before the skipped message is committed or before the message is moved. If a callback throws, the policy isn't applied, the message isn't committed and the consumer stops, so that the message will be consumed again once the consumer is restarted.
The IStopConsumerErrorPolicyCallback is invoked whenever the error handling results in the consumer being stopped, even without an explicit ThenStop(). It's also invoked when the error handling itself fails, for example because another callback throws or the message can't be moved; in that case, an exception thrown by the stop callback is logged but doesn't replace the original one.
Publish Events (Obsolete)
The Publish method, used to publish a message to the internal Using the Message Bus when the policy is applied, is obsolete and will be removed in the next major version. Use a callback instead, injecting the IPublisher if you need to publish a message:
public class SkippedMessagesNotifier : ISkipMessageErrorPolicyCallback
{
    private readonly IPublisher _publisher;

    public SkippedMessagesNotifier(IPublisher publisher)
    {
        _publisher = publisher;
    }

    public Task OnSkippingMessageAsync(IRawInboundEnvelope envelope, Exception exception) =>
        _publisher.PublishAsync(new ProcessingFailedEvent(envelope, exception));
}
Note that the message passed to Publish was published after the policy had been applied, while the callbacks are invoked before it.
Batches, Chunking and Sequences
When the consumed messages are part of a sequence (a batch, a chunked message, etc.), the error policy is applied to the whole sequence:
- Batch processing (Batch Processing Consumed Messages): if the subscriber throws, the whole batch is rolled back.
Retryprocesses the whole batch again, andSkipskips all the messages in the batch. - Chunking (Consuming Chunked Messages): all chunks belonging to the same message are retried or skipped together. With MQTT, the chunks rejected by a client with batch processing are instead handled one by one, since chunking can't be combined with batch processing.
- MoveTo can't move a sequence: the policy logs a warning and is skipped, falling back to the next policy in the chain (or stopping the consumer, if there is none). Don't rely on
MoveTowith batch processing or chunked messages; useSkipwith a callback instead.
Warning
Error policies aren't supported when streaming is enabled via AllowStreaming() (see Streaming). Silverback rejects any policy other than the default stop policy in that case.
Kafka Considerations
The Kafka consumer polls the broker in a background loop, which pushes the consumed messages into a bounded buffer per partition (see LimitBackpressure in Consuming Messages). While a message is being retried, the partition doesn't advance; once the buffer is full, the loop waits and stops polling.
If no poll occurs within max.poll.interval.ms (5 minutes by default), the consumer is considered failed and is removed from the group, triggering a rebalance. When using long retry delays or many retries, make sure the total time spent retrying stays below that threshold, or increase it:
.AddConsumer("consumer1", consumer => consumer
    .WithGroupId("my-group")
    .WithMaxPollIntervalMs(600000)
    .Consume<MyMessage>("endpoint1", endpoint => endpoint
        .ConsumeFrom("my-topic")
        .OnError(policy => policy
            .Retry(5, retryPolicy => retryPolicy.WithInterval(TimeSpan.FromMinutes(1)))
            .ThenSkip())))
Other things to consider:
- Partitions are processed independently by default, so a retry only blocks the affected partition. With
ProcessAllPartitionsTogether()a retry blocks the consumption of all partitions. - Since a rollback seeks back to the failed offset, the messages already buffered for that partition are consumed again after the retry.
- For long-lasting failures, prefer moving the message to a retry or dead letter topic over long in-process retries.
MQTT Considerations
MQTT can't re-read messages from the broker: the retry policy reprocesses the message that is held locally, and the message is acknowledged only after it has been successfully processed, skipped or moved.
- While a message is being retried, the processing channel it belongs to is blocked. With the default sequential processing, this means that the whole client stops processing messages. With parallel processing, the other channels keep processing only until the buffer of the blocked channel is full, since the messages are distributed round-robin; consider
EnableParallelProcessing(see Parallel Processing and Backpressure). - The broker only delivers a limited number of unacknowledged QoS 1/2 messages (Receive Maximum, configurable via
LimitUnacknowledgedPublications), so new messages stop flowing until the failed message is acknowledged. - If the client disconnects while retrying, the unacknowledged message is redelivered by the broker only if a persistent session and QoS 1 or 2 are used.
- With MQTT 3.1.1, headers aren't supported, so the failed attempts count can't be transferred with moved messages (see Failed Attempts Header).
Custom Policies
You can implement your own policy by implementing IErrorPolicy, which builds the actual IErrorPolicyImplementation, and passing an instance to OnError.
public class MyErrorPolicy : IErrorPolicy
{
    public IErrorPolicyImplementation Build(IServiceProvider serviceProvider) =>
        new MyErrorPolicyImplementation(serviceProvider.GetRequiredService<IMyAuditService>());

    private sealed class MyErrorPolicyImplementation : IErrorPolicyImplementation
    {
        private readonly IMyAuditService _auditService;

        public MyErrorPolicyImplementation(IMyAuditService auditService)
        {
            _auditService = auditService;
        }

        public bool CanHandle(ConsumerPipelineContext context, Exception exception) =>
            exception is MyRecoverableException;

        public async Task<bool> HandleErrorAsync(ConsumerPipelineContext context, Exception exception)
        {
            await _auditService.TrackFailureAsync(context.Envelope, exception);

            // Roll back the transaction and commit the consumer, to skip the message
            await context.TransactionManager.RollbackAsync(exception, commitConsumer: true);

            return true;
        }
    }
}
.Consume<MyMessage>("endpoint1", endpoint => endpoint
    .ConsumeFrom("my-topic")
    .OnError(new MyErrorPolicy()))
HandleErrorAsync returns true if the error was handled, or false to rethrow the exception and stop the consumer. The implementation is responsible for completing the consumer transaction via the IConsumerTransactionManager.
Alternatively, derive from ErrorPolicyBase and ErrorPolicyImplementation to benefit from the built-in support for the apply rules and the maximum attempts.
Tip
Look at the built-in policies (for example SkipMessageErrorPolicy and RetryErrorPolicy) for a reference on how to interact with the transaction manager.